
Watch someone pour almonds into a bowl, and the action is easy to follow: a container moves, tilts and releases its contents. Teaching a robot to do the same can require costly demonstrations specifying how its joints and gripper should move.
University of Maryland researchers have developed an artificial intelligence model that learns from videos how hands, tools and objects move and then uses those patterns to help robots perform tasks.
Called μ₀, or Mu Zero, it is a type of AI called a world model, which predicts how a scene will change during an activity. Given an image and an instruction, such as “place the cup in the sink,” Mu Zero predicts how selected points on objects will move through three-dimensional space.
In tests with a robot arm, the system outperformed several competing approaches at placing objects in a sink, pouring almonds and unfolding a towel.
The team includes UMD computer science associate professors Furong Huang and Jia-Bin Huang and collaborators at UMD and Seoul National University. Both professors hold appointments in the University of Maryland Institute for Advanced Computer Studies (UMIACS). Furong Huang is also a core faculty member in the UMD Center for Machine Learning.
Their paper, “μ₀: A Scalable 3D Interaction-Trace World Model,” earned the second-place Best Paper Award at the IROS 2026 RoBoWoMo workshop in late September. It has also been accepted for presentation in November at the Conference on Robot Learning.
The project addresses a stubborn obstacle: videos of physical activities are plentiful, but recordings paired with precise robot commands are expensive to collect. Those commands are also hardware-specific; instructions for one robot’s arm may not translate to another.
Some AI approaches predict what happens next by generating future video frames, devoting substantial computing capacity to recreating appearances and backgrounds. Others predict robot commands directly, tying their training to specific machines.
Mu Zero focuses on movement, representing the paths of selected points on hands, tools and objects—including where they make contact—as smooth curves called traces.
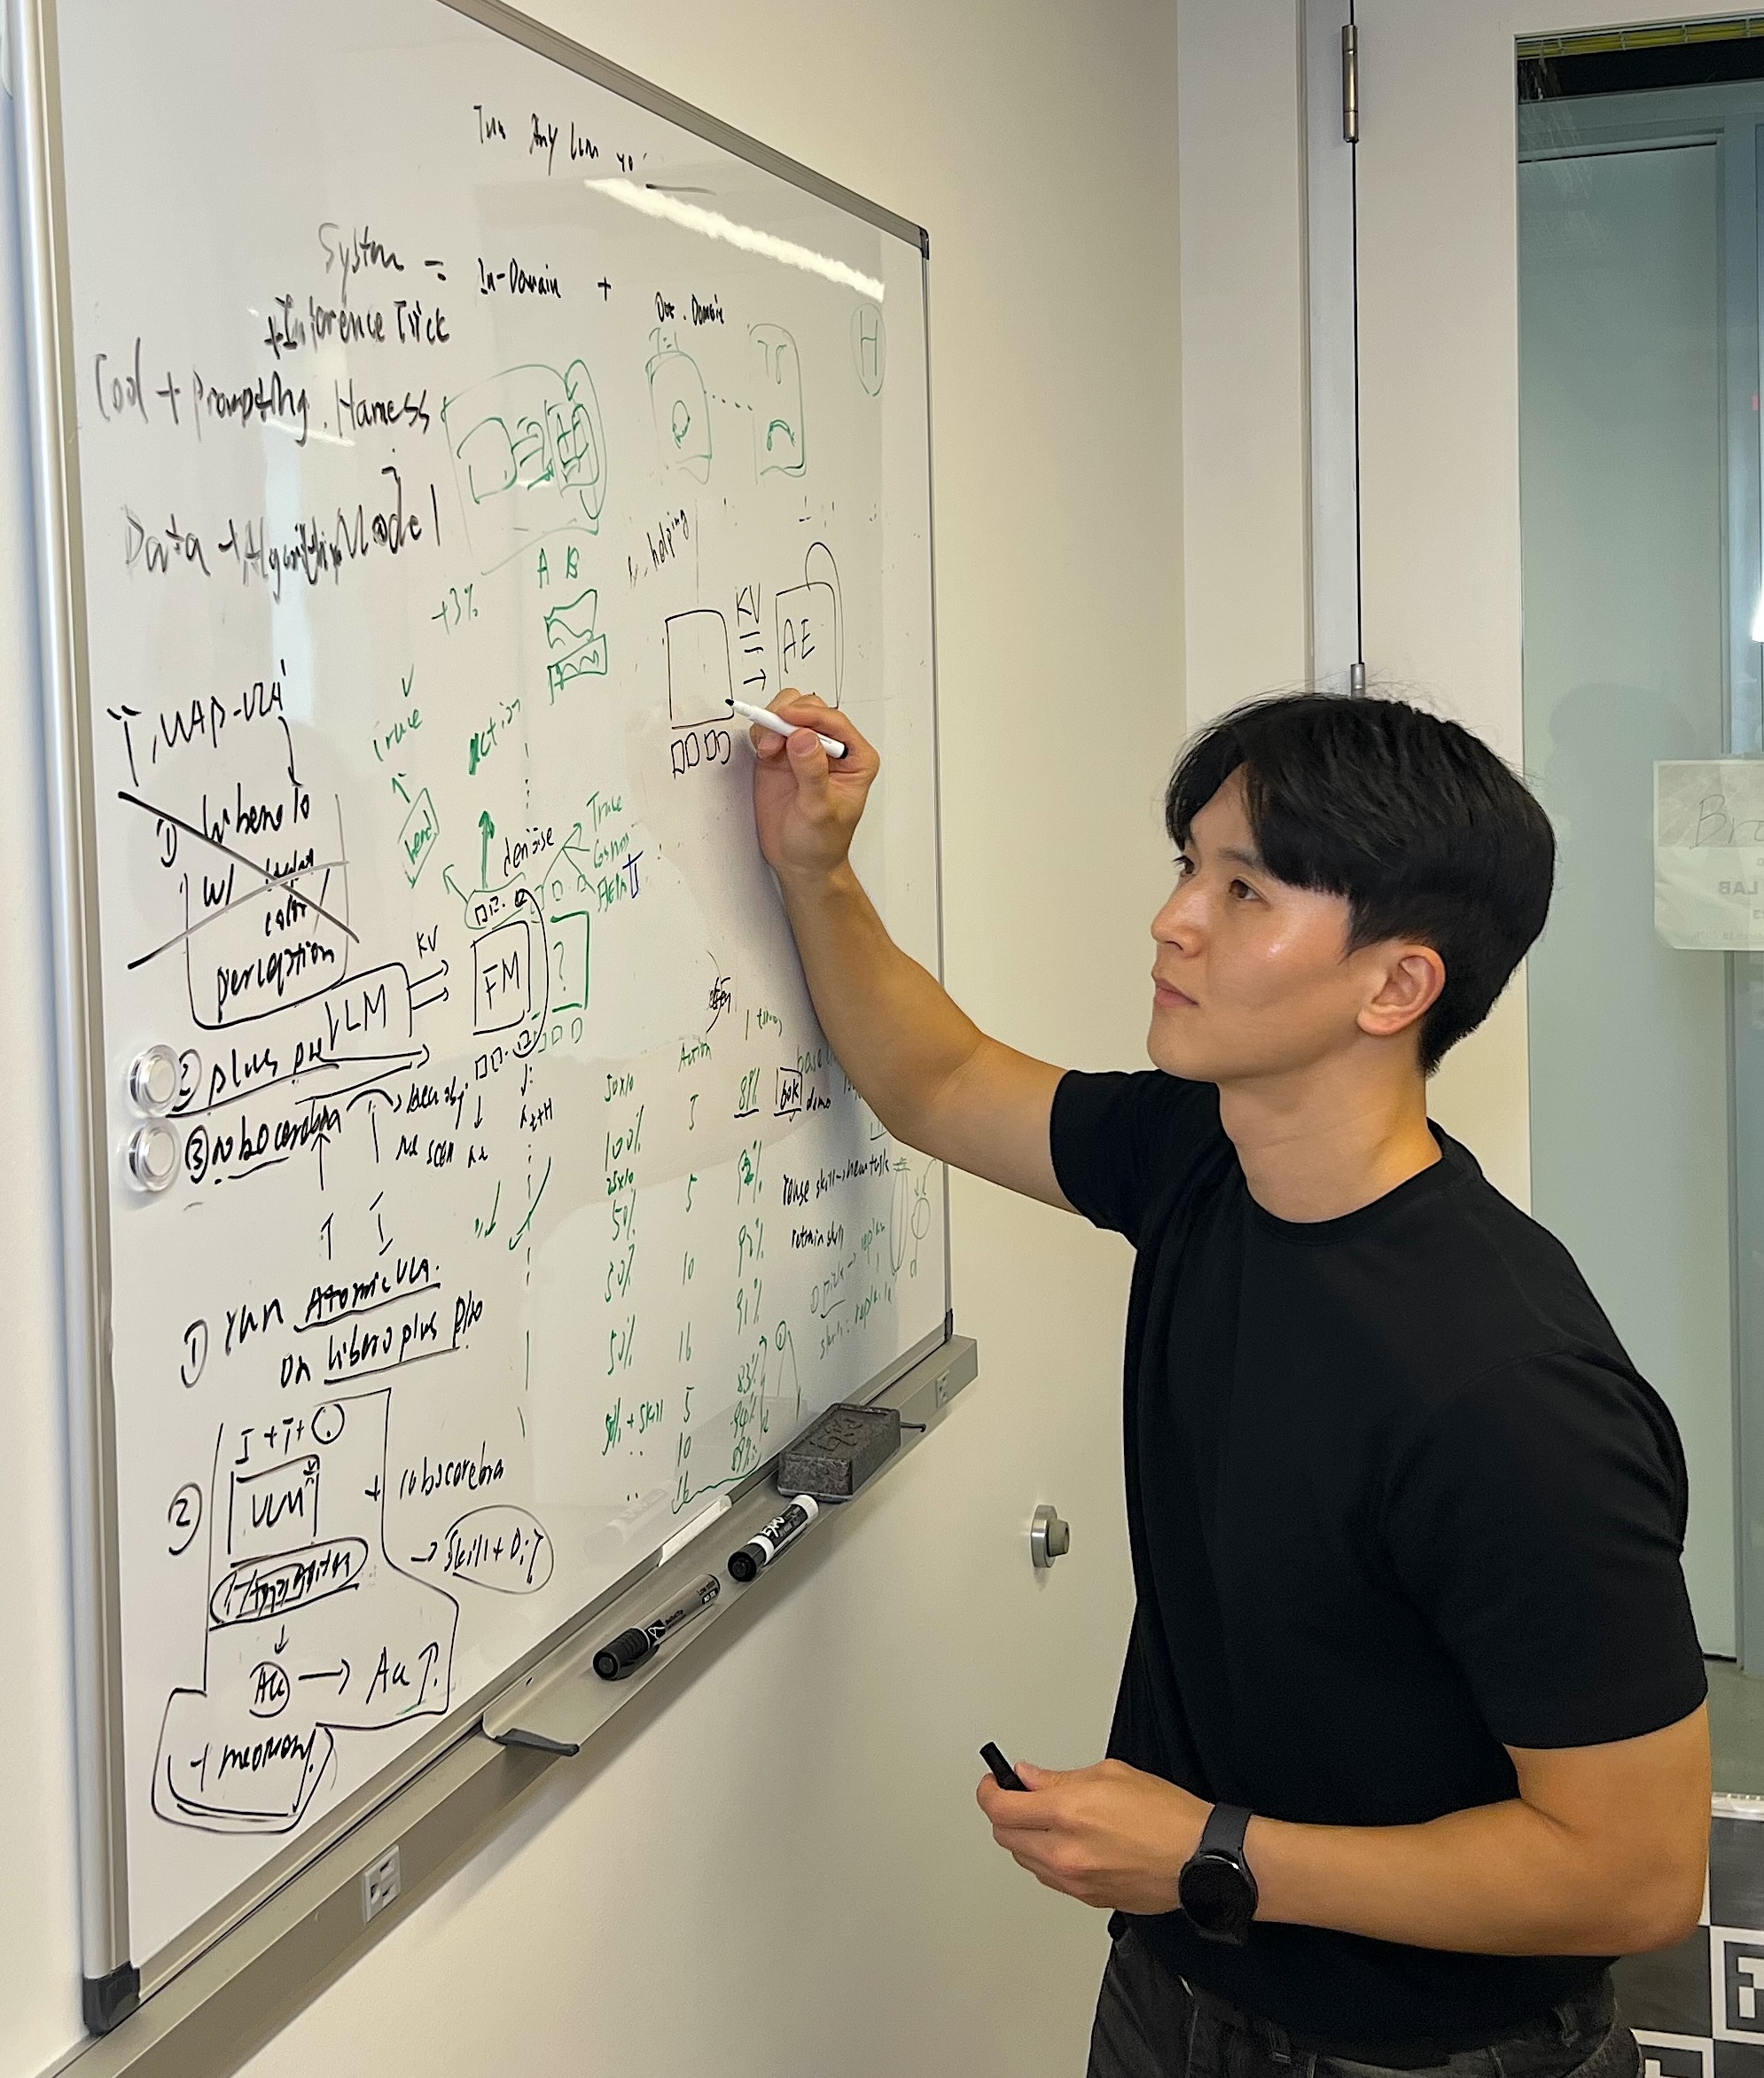
“Think of it as tracing the choreography of a task. When a cup moves toward a sink, the useful information includes where the cup travels and how it turns,” said Seungjae “Jay” Lee, a UMD computer science doctoral student and co-lead author of the paper. “The model represents that movement with smooth curves, preserving spatial information without reconstructing every pixel.”
Those visible paths also help researchers inspect the model’s predictions, added Lee, who is co-advised by Furong Huang and Jia-Bin Huang.
To create training data, the team developed TraceExtract, a system that converts human and robot videos into motion traces paired with descriptions. It selects meaningful points, tracks their movement in three dimensions and pairs individual motion events with language descriptions. It also distinguishes object movement from camera movement.
Mu Zero learns to forecast these traces. A separate component, called an action expert, learns to translate information from the model into commands for a specific robot.
Mu Zero’s initial training on video requires no accompanying robot commands, although the action expert still learns from robot demonstrations. The world model remains fixed during that adaptation, allowing its motion knowledge to be reused.
“Our approach separates learning what needs to move from learning how a particular machine can make that movement happen,” said co-lead author Yoonkyo Jung, a UMD doctoral student in electrical and computer engineering advised by Furong Huang.
In physical experiments, a robot arm with a two-finger gripper achieved an average success rate of 91.7% across three tasks, exceeding two competing systems by 20 and 11.7 percentage points, respectively.
Simulation results were mixed. Across eight kitchen tasks, Mu Zero achieved a 30.25% average success rate, ahead of one competitor’s 25.25% but below the other’s 42%. It also outperformed earlier methods for predicting motion traces in two and three dimensions.
“This work contributes to physical intelligence—AI systems that connect perception and language with movement in the world,” said Furong Huang. “Learning reusable motion patterns from videos could reduce dependence on costly, hardware-specific training data.”
She noted that the system still has limits. Tracking and captioning errors can affect learning, and the model does not explicitly account for forces or touch. Its performance on a broader range of robots and tasks remains untested.
The experiments nevertheless demonstrate a useful division of labor, she explained: videos teach the model how objects move, while robot demonstrations teach a specific machine how to carry out those movements. That separation allows the system to learn from recordings that contain no detailed robot commands.
—Story by UMIACS communications group